
High-dimensional Data Analysis in Cancer Research pdf epub mobi txt 电子书 下载 2026
- 统计学
- 机器学习
- 人工智能
- 癌症研究
- 高维数据
- 生物信息学
- 数据分析
- 机器学习
- 统计学
- 基因组学
- 蛋白质组学
- 生物医学
- 计算生物学

具体描述
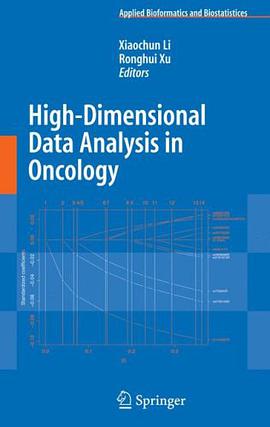
Multivariate analysis is a mainstay of statistical tools in the analysis of biomedical data. It concerns with associating data matrices of n rows by p columns, with rows representing samples (or patients) and columns attributes of samples, to some response variables, e.g., patients outcome. Classically, the sample size n is much larger than p, the number of variables. The properties of statistical models have been mostly discussed under the assumption of fixed p and infinite n. The advance of biological sciences and technologies has revolutionized the process of investigations of cancer. The biomedical data collection has become more automatic and more extensive. We are in the era of p as a large fraction of n, and even much larger than n. Take proteomics as an example. Although proteomic techniques have been researched and developed for many decades to identify proteins or peptides uniquely associated with a given disease state, until recently this has been mostly a laborious process, carried out one protein at a time. The advent of high throughput proteome-wide technologies such as liquid chromatography-tandem mass spectroscopy make it possible to generate proteomic signatures that facilitate rapid development of new strategies for proteomics-based detection of disease. This poses new challenges and calls for scalable solutions to the analysis of such high dimensional data. In this volume, we will present the systematic and analytical approaches and strategies from both biostatistics and bioinformatics to the analysis of correlated and high-dimensional data.
作者简介
目录信息
读后感
用户评价
相关图书









本站所有内容均为互联网搜索引擎提供的公开搜索信息,本站不存储任何数据与内容,任何内容与数据均与本站无关,如有需要请联系相关搜索引擎包括但不限于百度,google,bing,sogou 等
© 2026 book.wenda123.org All Rights Reserved. 图书目录大全 版权所有